Apple Mac mini M4 Pro 64GB vs NVIDIA Jetson Thor T4000
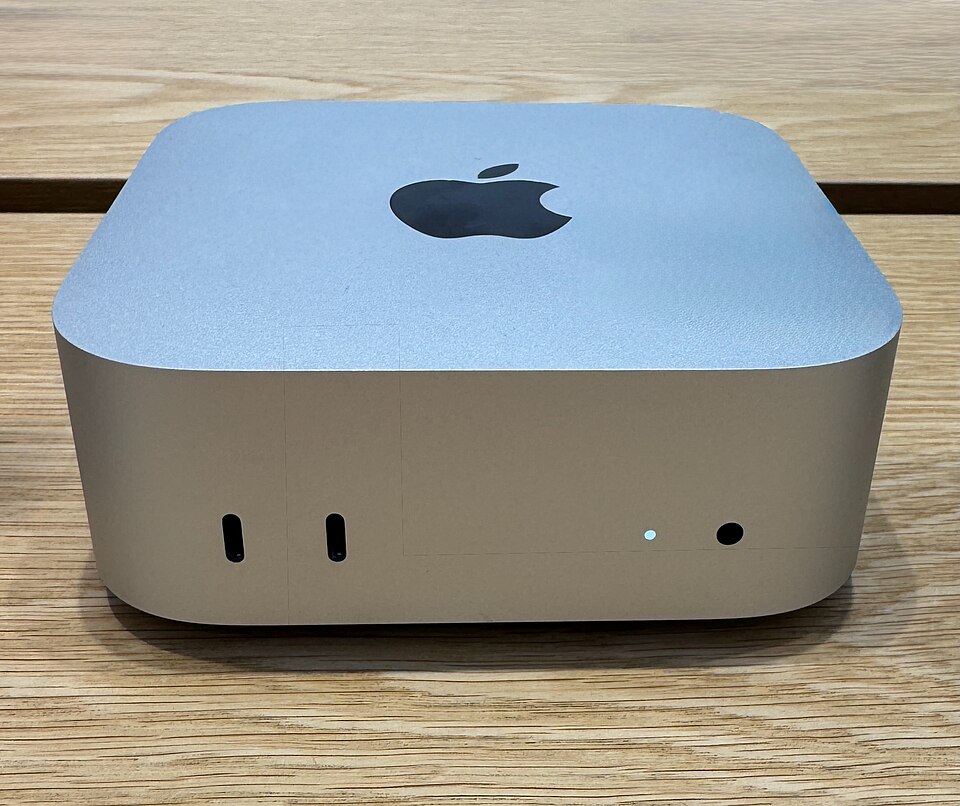

No like-for-like comparison yet: both have published results, but model size or batch differ. Treat the numbers below as indicative only.
| Apple Mac mini M4 Pro 64GB | NVIDIA Jetson Thor T4000 | |
|---|---|---|
| Best LLM generation | 5.48 tok/s C 2026 (year only) | 423 tok/s C undated |
| Power | 80.00 W measured | n/a |
| Perf / W | 0.0685 tok/s/W measured | n/a |
| Price | n/a | n/a |
| Workloads with data | 1 of 7 | 1 of 7 |
Best published LLM generation result per platform. n/a = not published; never estimated.
Show data — all workloads, sources and like-for-like groups
object detection
No published object detection results for Apple Mac mini M4 Pro 64GB or NVIDIA Jetson Thor T4000 yet.
We only show cited public figures — nothing is estimated to fill gaps. Requests tell us what to source or test next.
instance segmentation
No published instance segmentation results for Apple Mac mini M4 Pro 64GB or NVIDIA Jetson Thor T4000 yet.
We only show cited public figures — nothing is estimated to fill gaps. Requests tell us what to source or test next.
pose estimation
No published pose estimation results for Apple Mac mini M4 Pro 64GB or NVIDIA Jetson Thor T4000 yet.
We only show cited public figures — nothing is estimated to fill gaps. Requests tell us what to source or test next.
image classification
No published image classification results for Apple Mac mini M4 Pro 64GB or NVIDIA Jetson Thor T4000 yet.
We only show cited public figures — nothing is estimated to fill gaps. Requests tell us what to source or test next.
semantic segmentation
No published semantic segmentation results for Apple Mac mini M4 Pro 64GB or NVIDIA Jetson Thor T4000 yet.
We only show cited public figures — nothing is estimated to fill gaps. Requests tell us what to source or test next.
speech-to-text
No published speech-to-text results for Apple Mac mini M4 Pro 64GB or NVIDIA Jetson Thor T4000 yet.
We only show cited public figures — nothing is estimated to fill gaps. Requests tell us what to source or test next.
LLM generation
| Platform | Result | Model · precision · stack | Grade | Power | Source |
|---|---|---|---|---|---|
| NVIDIA Jetson Thor T4000 | 35.00 tok/s generation_throughput · b=1 | Qwen 3 8B NVFP4 · vLLM · LLM 5–14B | C | unknown power n/a no power published | NVIDIA Jetson AI Lab benchmarks (benchmarks.json) undated |
| Apple Mac mini M4 Pro 64GB MIXED: model-size class LLM >40B vs LLM 5–14B; batch unknown vs 1 | 5.48 tok/s tg · b=unknown | 70B-class LLM (Q4) ~Q4 · as reviewed (Ollama/llama.cpp class) · LLM >40B | C | 80.00 W measured reported in result source — measured | vminstall.com review 2026 (year only) |
No shared like-for-like group exists for this pair.
How to read these numbers
Machine-readable: /find.json (see llms.txt); full tables are in “Show data”. Confidence grades: A audited MLPerf closed · B documented third-party · C community · D vendor-published · E estimate. Unknown values are shown as unknown, never estimated. Generated 2026-10-16 from public sources.